Introducing Simons
Frontier time series forecasting, built with automated research. Open weights, training code and public training data.
We're introducing Simons, a family of open time series foundation models. Starting from a minimal baseline in nanoTSFM, we reached frontier forecasting on public benchmarks in about two weeks using automated research, and the whole effort took less than $8,000 of GPU time.
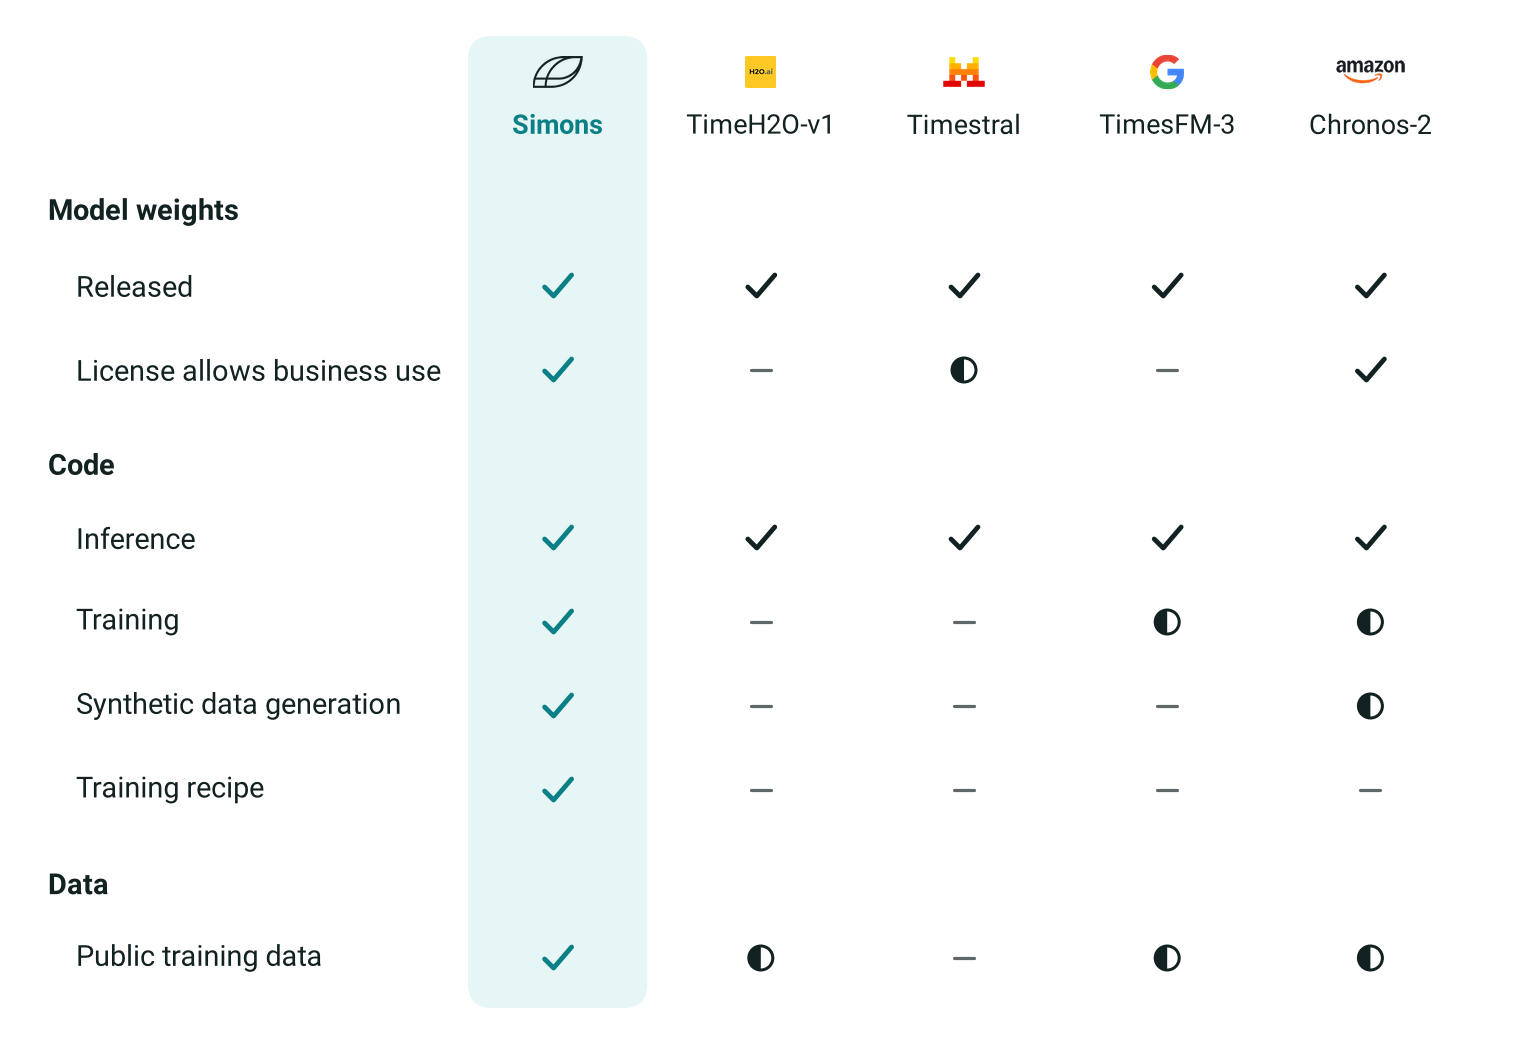
We are releasing the complete training code, the synthetic data generators, the public training data and the weights so that anyone can start from a frontier model and build on it. To our knowledge, that makes Simons the strongest forecasting model that is open down to its training code.
Simons does zero-shot forecasting: it needs no training on your data. Give it the history of a series, such as hourly electricity demand, and it forecasts what comes next at several quantiles, giving you both a central estimate and a prediction interval.
Performance and speed
Simons ranks fourth among open-weight models on GIFT-Eval, fev-bench and TIME, each scored by its own measure, ahead of TimesFM-3, Toto-2.0 and Chronos-2. The same checkpoints carry over to further public benchmarks that do not overlap our training data, taking first place on the M6 forecasting competition benchmark. During development, GIFT-Eval and fev-bench guided the choice between candidate models; TIME did not.
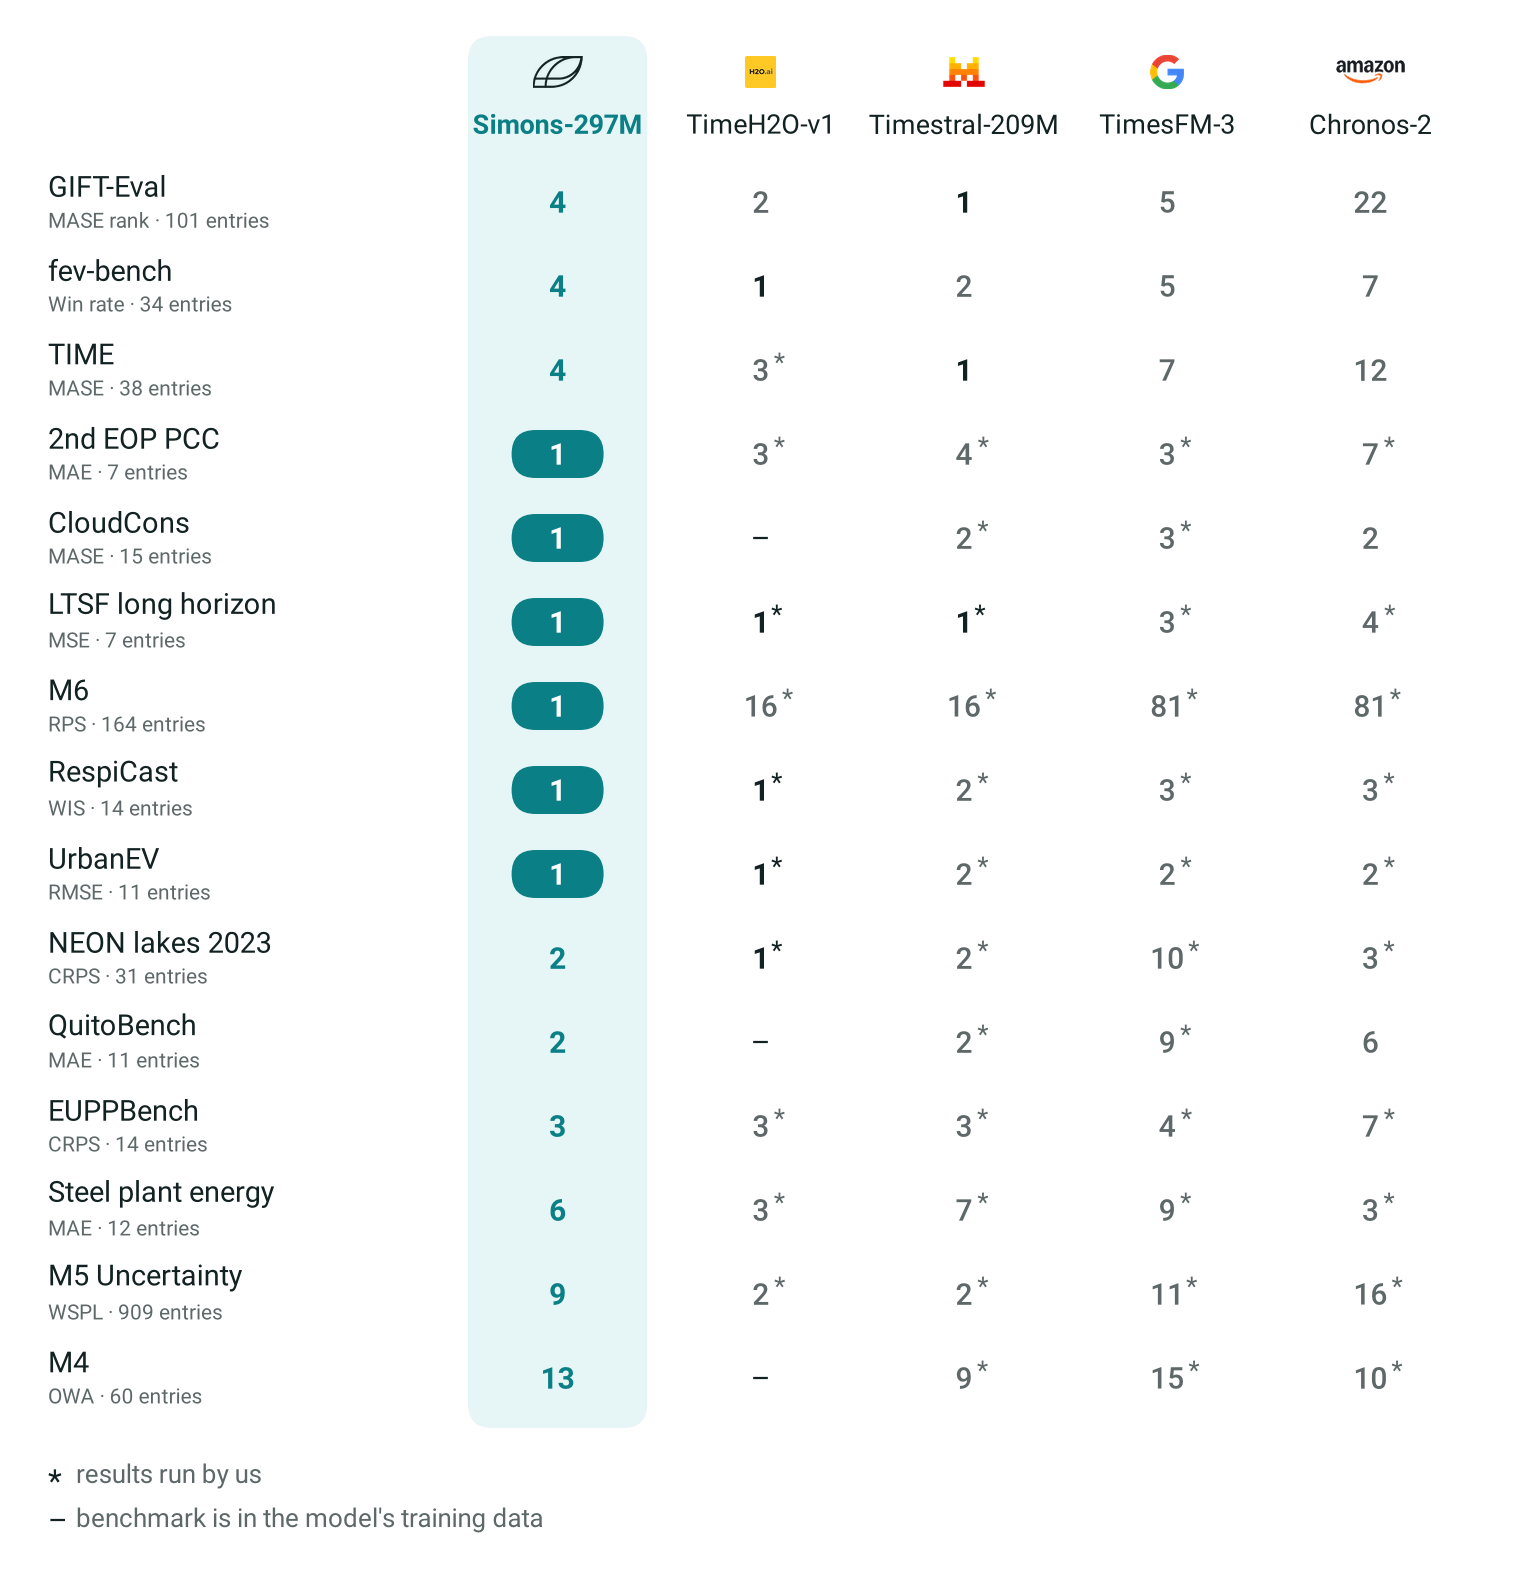
Accuracy only helps in practice if forecasts finish before the next decision is due. Simons runs all of GIFT-Eval in under a quarter of an hour on a single A100 GPU, about twenty times faster than leading models of similar size, which take four to five hours. Across the three leaderboards it is about ten times faster, each model run with the settings behind its leaderboard score.
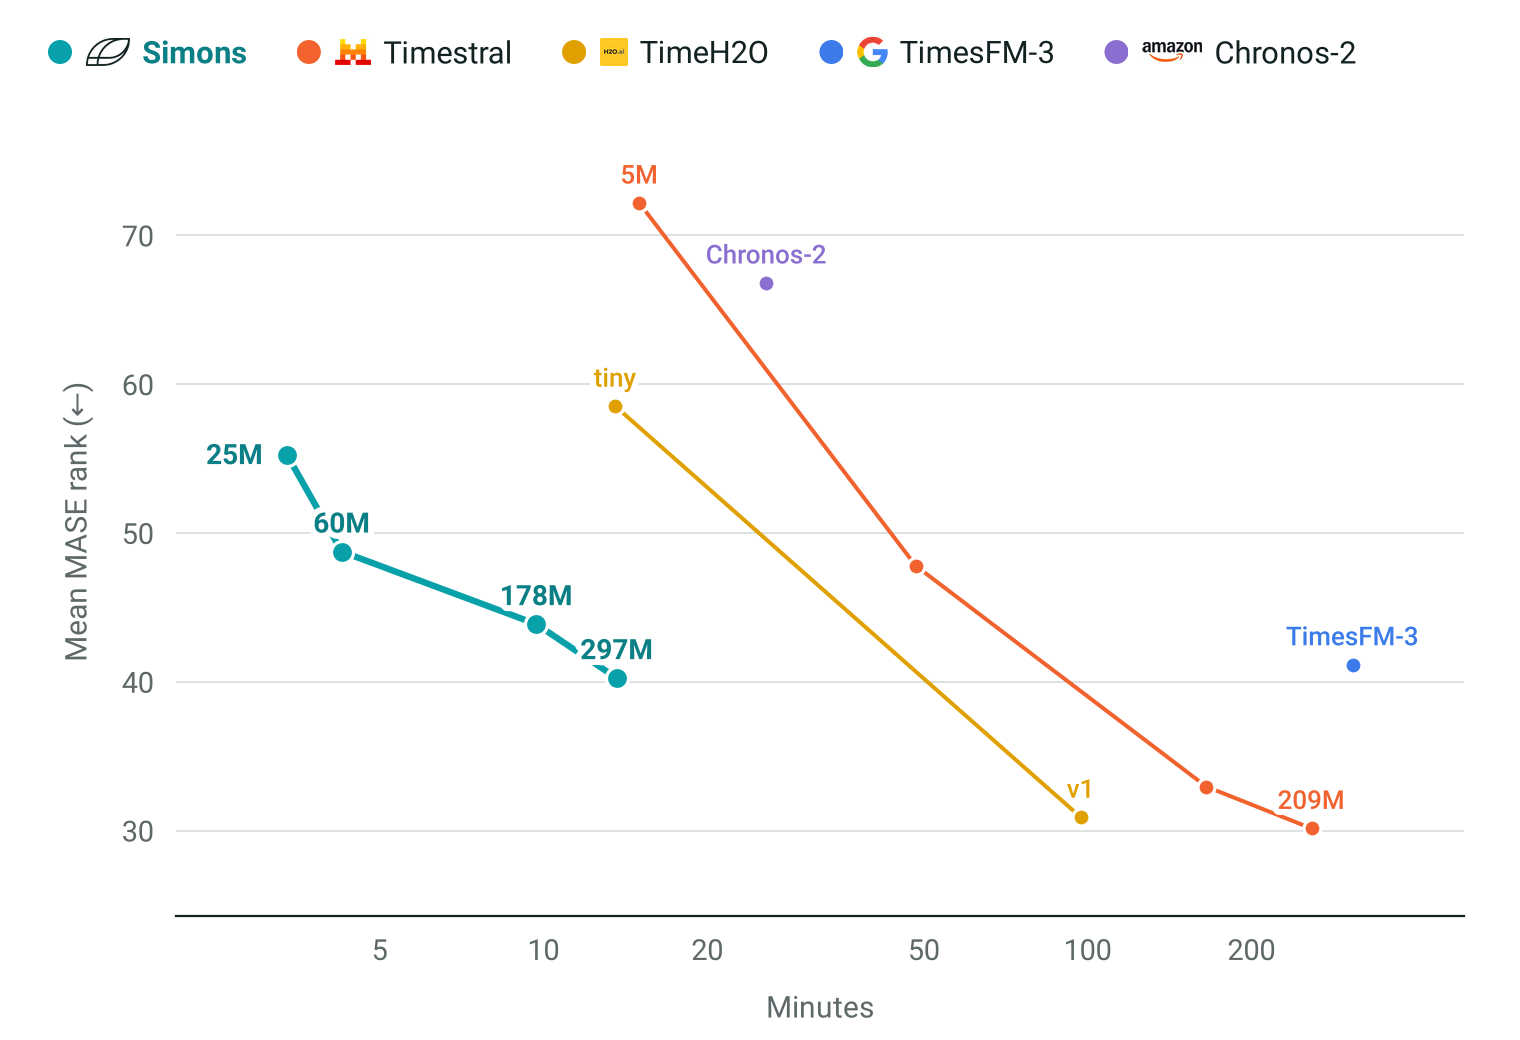
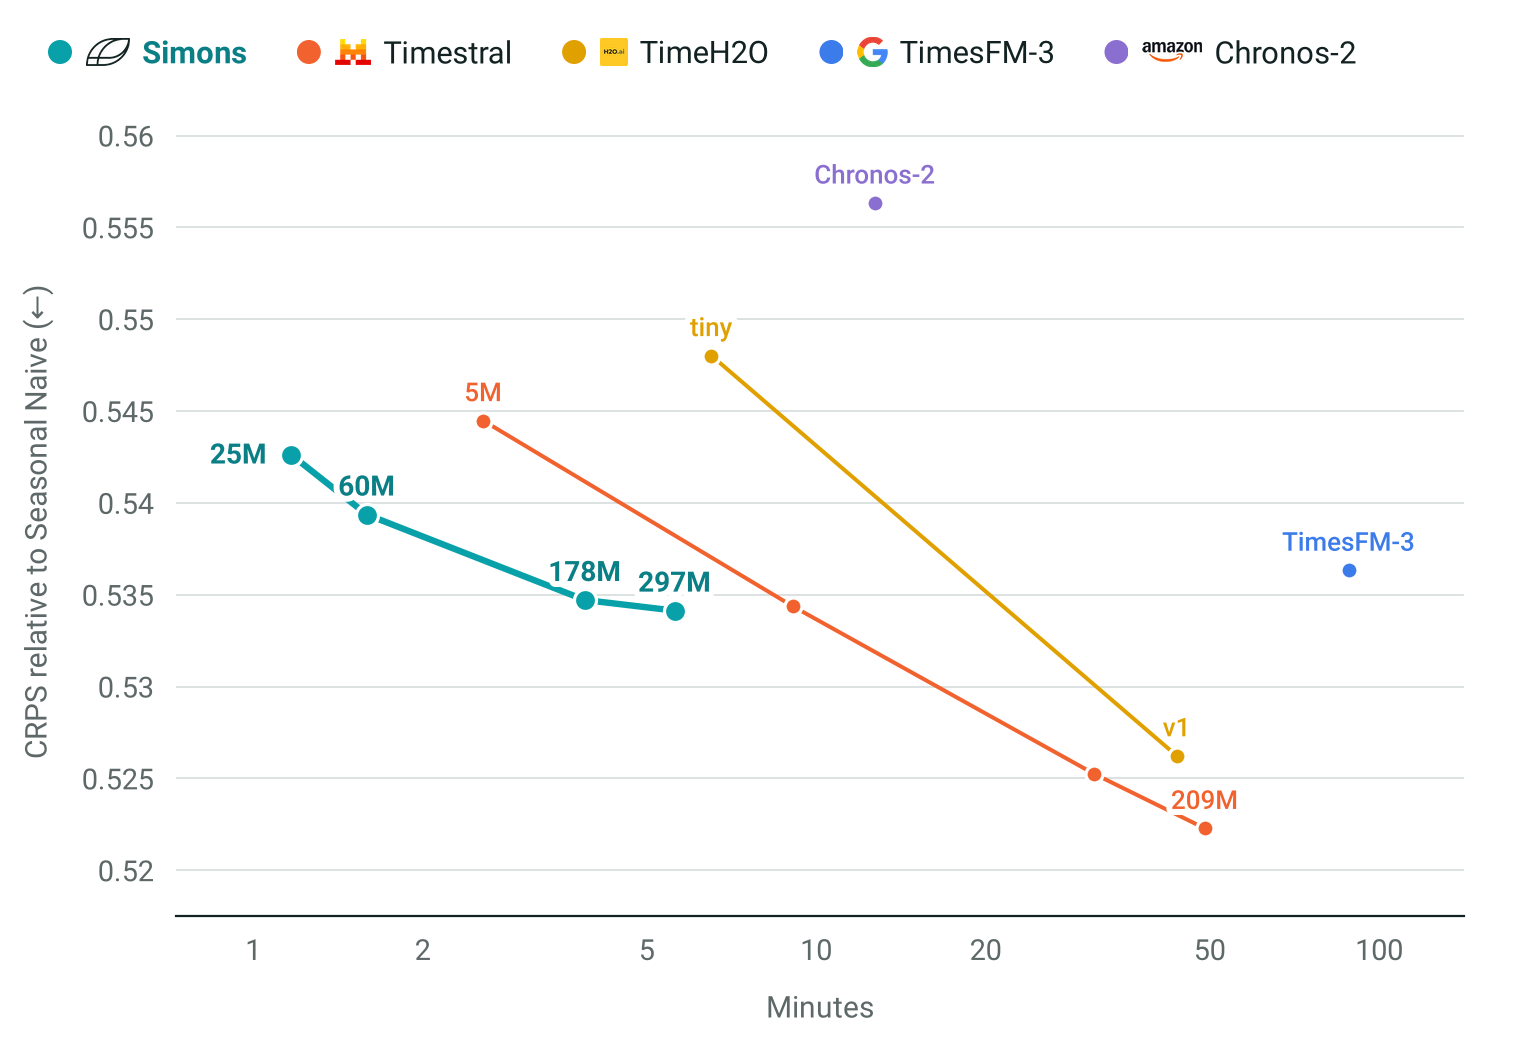
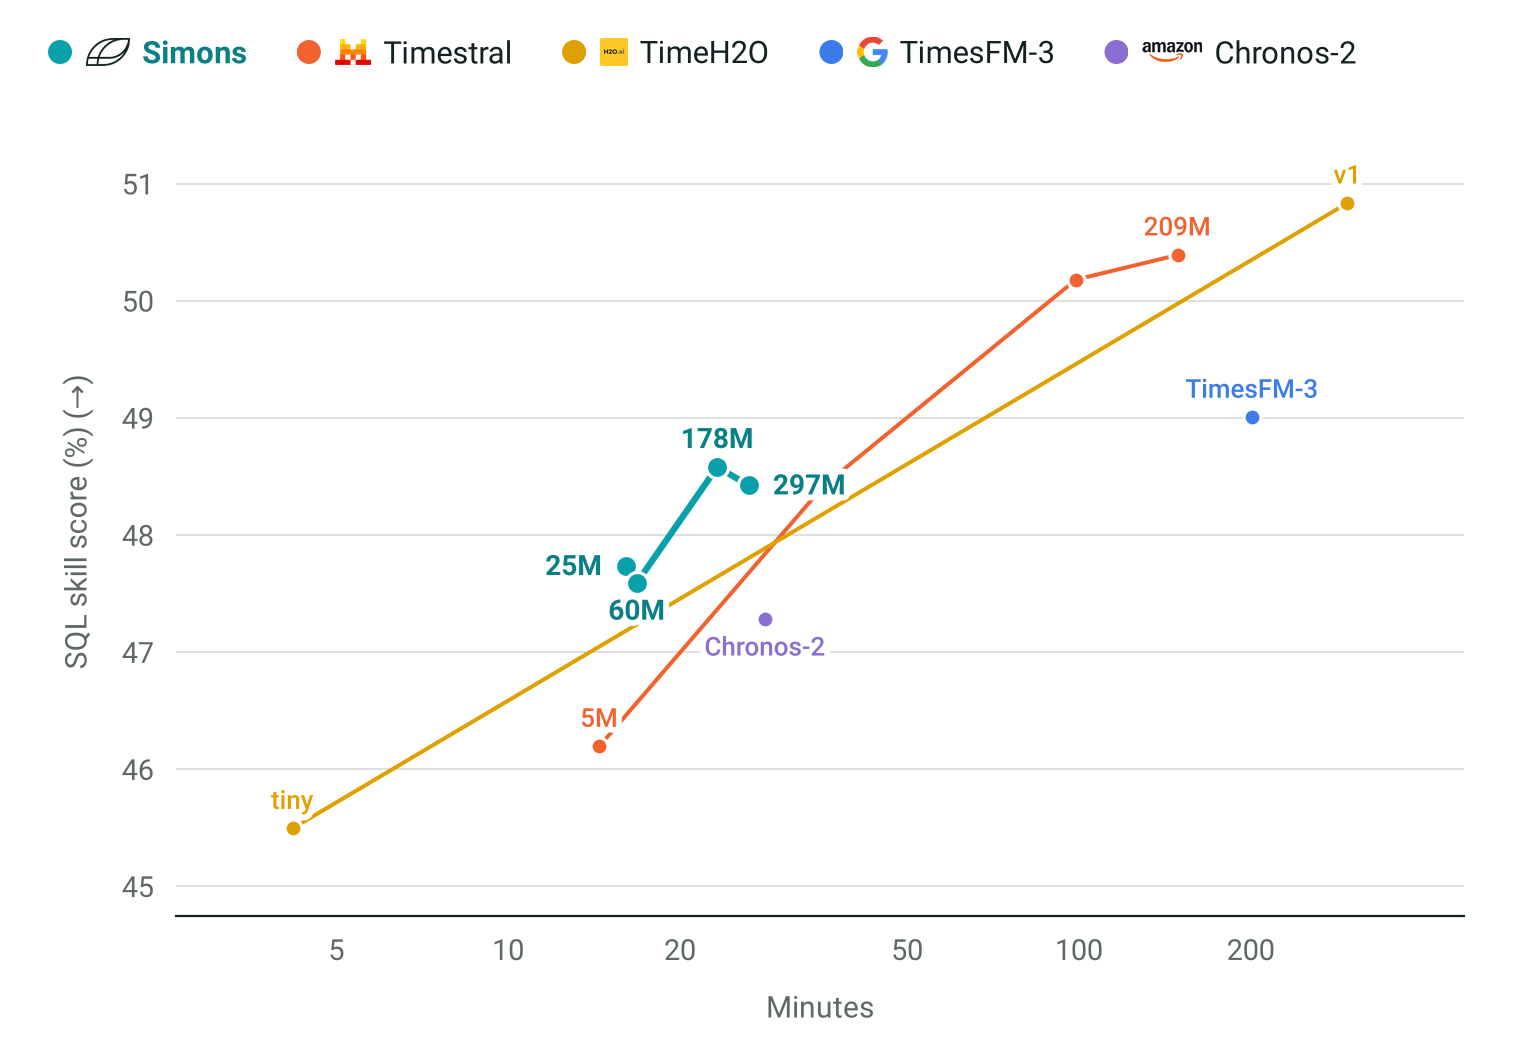
Score against the minutes a model takes to forecast the whole benchmark on one A100 GPU, each model with its leaderboard settings, on GIFT-Eval, TIME and fev-bench. A line joins the sizes of a model family; the time axis is logarithmic. To the left is faster; on GIFT-Eval and TIME a lower score is better, on fev-bench a higher one.
How Simons is built
Simons was developed through an automated research system that turns model design into a disciplined, parallel search. Our team built the system, set the goals and evaluation rules, and supplied the data and compute.
Within it, each research direction moves through a tight loop around a shared knowledge store. A proposer reads earlier experiment reports and the literature to frame a hypothesis. A researcher then edits the training pipeline and iterates under a fixed compute budget, picking its best candidate from validation scores alone. To keep noise and lucky runs out, a confirmation step rebuilds that candidate with fixed code and retrains it on reserved random seeds. Finally, a reflection step writes down what worked and why into the shared store. An orchestrator runs several loops at once, letting promising directions build on earlier recipes or merge separate lines of work, so confirmed gains compound rather than get lost between runs. The agents cannot modify the evaluation code or see benchmark labels.
The auto-research loop: a proposer, a researcher, a confirmation step and a reflection step around a shared knowledge store, with an orchestrator running several loops in parallel.
The search started from a baseline of about three million parameters in nanoTSFM, our minimal environment for time series foundation models. Within the first day, forecasting error had already fallen on that same small model, for a few dozen dollars of GPU time. The models then grew as the search went on, passing well-known models along the way: Sundial in the first two days, Chronos-2 and Toto-2.0 within the first week. After about two weeks, the full-size model ranked ahead of TimesFM-3 on GIFT-Eval by mean MASE rank, the average of a model's places across tasks, while TimesFM-3 remains slightly ahead on aggregate MASE itself. A second campaign of about five days then added known-future covariates and produced the four released sizes.
Across both campaigns the system explored more than two hundred and fifty research directions and attempted nearly two thousand experiments, most of them on small models. About three quarters of the first campaign's gain came from data and from how a series enters the model, including synthetic data, the data mixture and transformations applied at forecast time. About a fifth came from the optimizer and training schedule, while changes to the backbone contributed little. Most single ideas were too small to pass confirmation alone; they added up through successive directions and merges.
Inside Simons
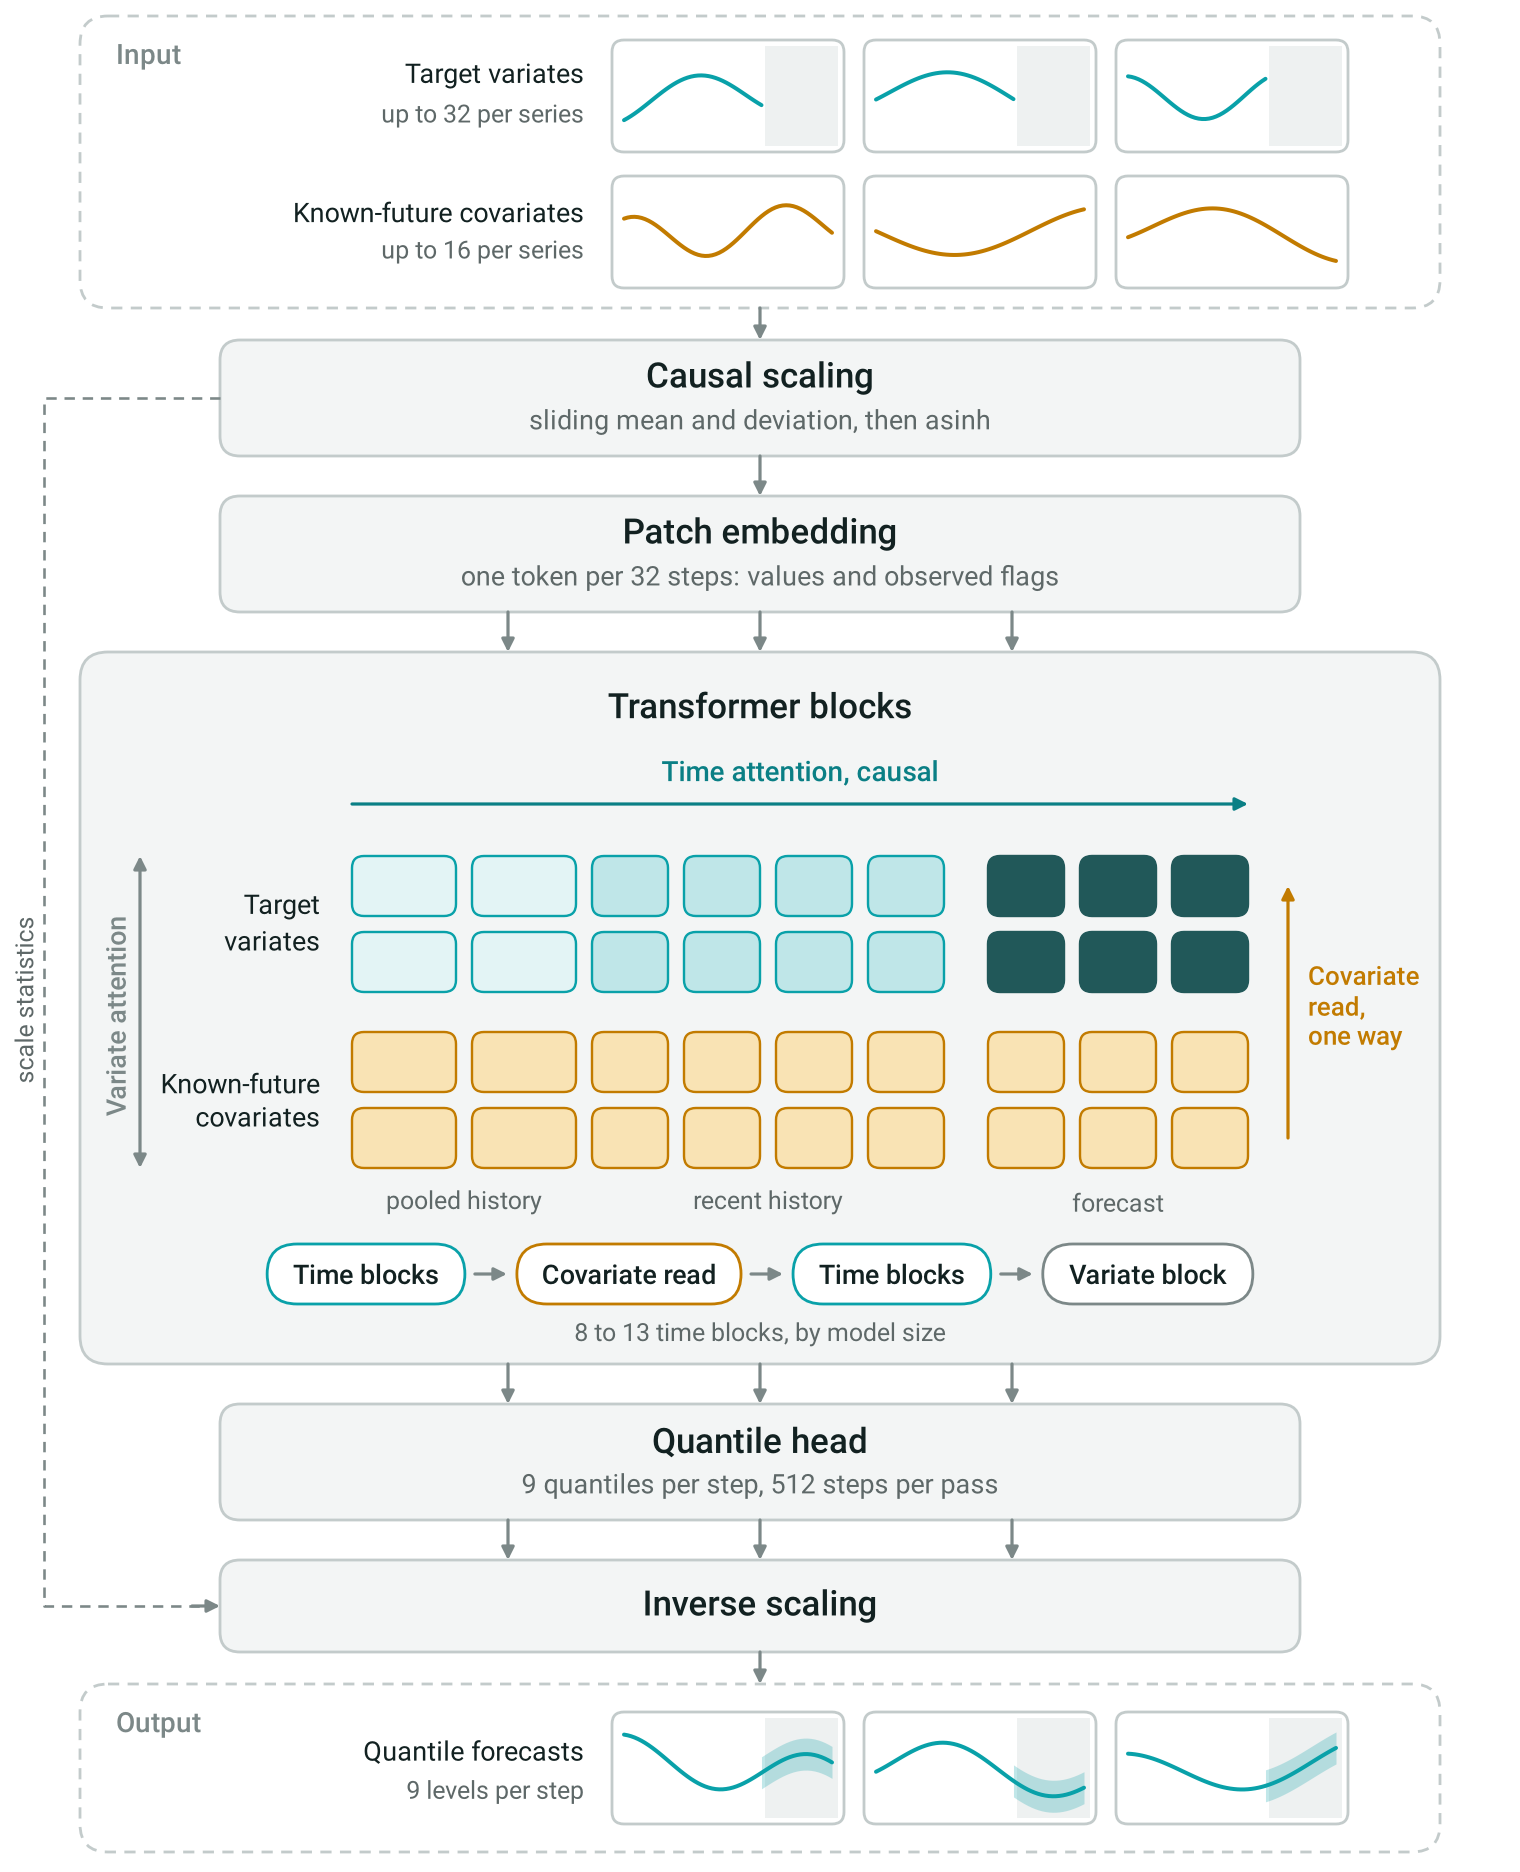
Often a forecaster knows more than past values alone: a weather forecast, a scheduled promotion, or a public holiday calendar. Simons takes these as known-future covariates alongside the history of the series. On German day-ahead electricity prices, giving Simons next-day forecasts of demand, wind generation and solar output cuts its forecasting error by more than half compared with forecasting from price history alone.
Forecast from Dec 28, 00:00Click or drag on the chart to move the start
Under the hood, the architecture stays deliberately plain. Each input series, with thousands of steps of history, is scaled and cut into patches of thirty-two time steps. A causal transformer attends along time while reading the known-future covariates one way, so covariates inform the forecast without being forecast themselves. A final layer attends across variates, and a quantile head predicts nine quantiles for hundreds of steps in one pass, forecasting longer horizons block by block.
Open in every way
We are open-sourcing Simons so that anyone can start from a frontier model and build on it, rather than starting from zero.
That is why we release the full stack behind the checkpoints: the weights, the training code, the synthetic data generators and our public training data. The models and the code come under permissive licenses that allow business use.
Get started
Download the models and the materials behind them here:
| What | Where | License |
|---|---|---|
| Code | github.com/Abel-ai-lab/Simons: training, the training recipe of every model, synthetic data generation, inference and benchmarks | Apache-2.0 |
| Model weights | Simons-25M, Simons-60M, Simons-178M, Simons-297M | OpenMDW-1.1 |
| Data | abel-lab/Simons-Pretrain, the public training data | OpenMDW-1.1 for the collection; each dataset keeps its own license |
| Tech report | Coming soon |
pip install "git+https://github.com/Abel-ai-lab/Simons"
What's next
At Abel AI Lab, we are building the other half of intelligence: foundation models that natively understand numbers and structured data, and the laws behind their dynamics. Simons is our starting point in forecasting.
Taking a minimal baseline to the frontier in about two weeks shows how much headroom remains in this class of models. We see automated research as a paradigm shift for structured foundation models at large, in time series and beyond. Next, we are extending Simons to richer covariates and larger scales while sharpening how our research loop decides what to try next.